Crawl Budget: Fix Waste First
Key takeaways
- Google's crawl budget guidance is mainly for very large, rapidly changing or heavily undiscovered sites.
- Crawl capacity and crawl demand are different constraints.
- Server logs show requested URLs, while Search Console Crawl Stats shows broader crawling patterns and host issues.
- Duplicate parameters, soft 404s, redirect chains and stale sitemap URLs can waste requests.
- Measure priority-page discovery and recrawl after a controlled fix.
Does every site have a crawl budget problem?
No. Google says its advanced crawl budget guidance is mainly for very large sites, medium or larger sites with rapidly changing content, and sites with many URLs marked Discovered, currently not indexed.
For a smaller well-linked site whose new pages are found promptly, an up-to-date sitemap and routine index coverage checks may be enough. Calling every indexing disappointment a crawl budget crisis is technically fashionable, but not especially diagnostic.
What is crawl budget?
Google defines crawl budget as the set of URLs its crawlers can and want to crawl. Crawl capacity is about how much the host can serve without being overwhelmed. Crawl demand reflects factors such as known URL inventory, popularity, staleness and content value.
That distinction changes the remedy. More server capacity may help a host that is genuinely constrained. It will not make duplicate or low-value URLs more useful.
How do you prove crawl waste?
Prove crawl waste by combining Crawl Stats, server logs and a classified URL inventory. Google's crawling error guide says Crawl Stats can expose host availability patterns, while server logs can show when specific paths were requested.
Group requests by template and parameter pattern. Record status code, response time, canonical target, indexability and business purpose. Compare the share of requests going to priority pages with duplicates, errors, internal search, filters and obsolete URLs.
A giant log export is not yet an insight. It is merely a spreadsheet asking for adult supervision.
Which URL patterns usually waste crawling?
Waste commonly appears in faceted navigation, duplicate parameters, session identifiers, soft 404s and long redirect chains. Google's faceted navigation guidance warns that filter combinations can create near-infinite URL spaces and slower discovery crawls.
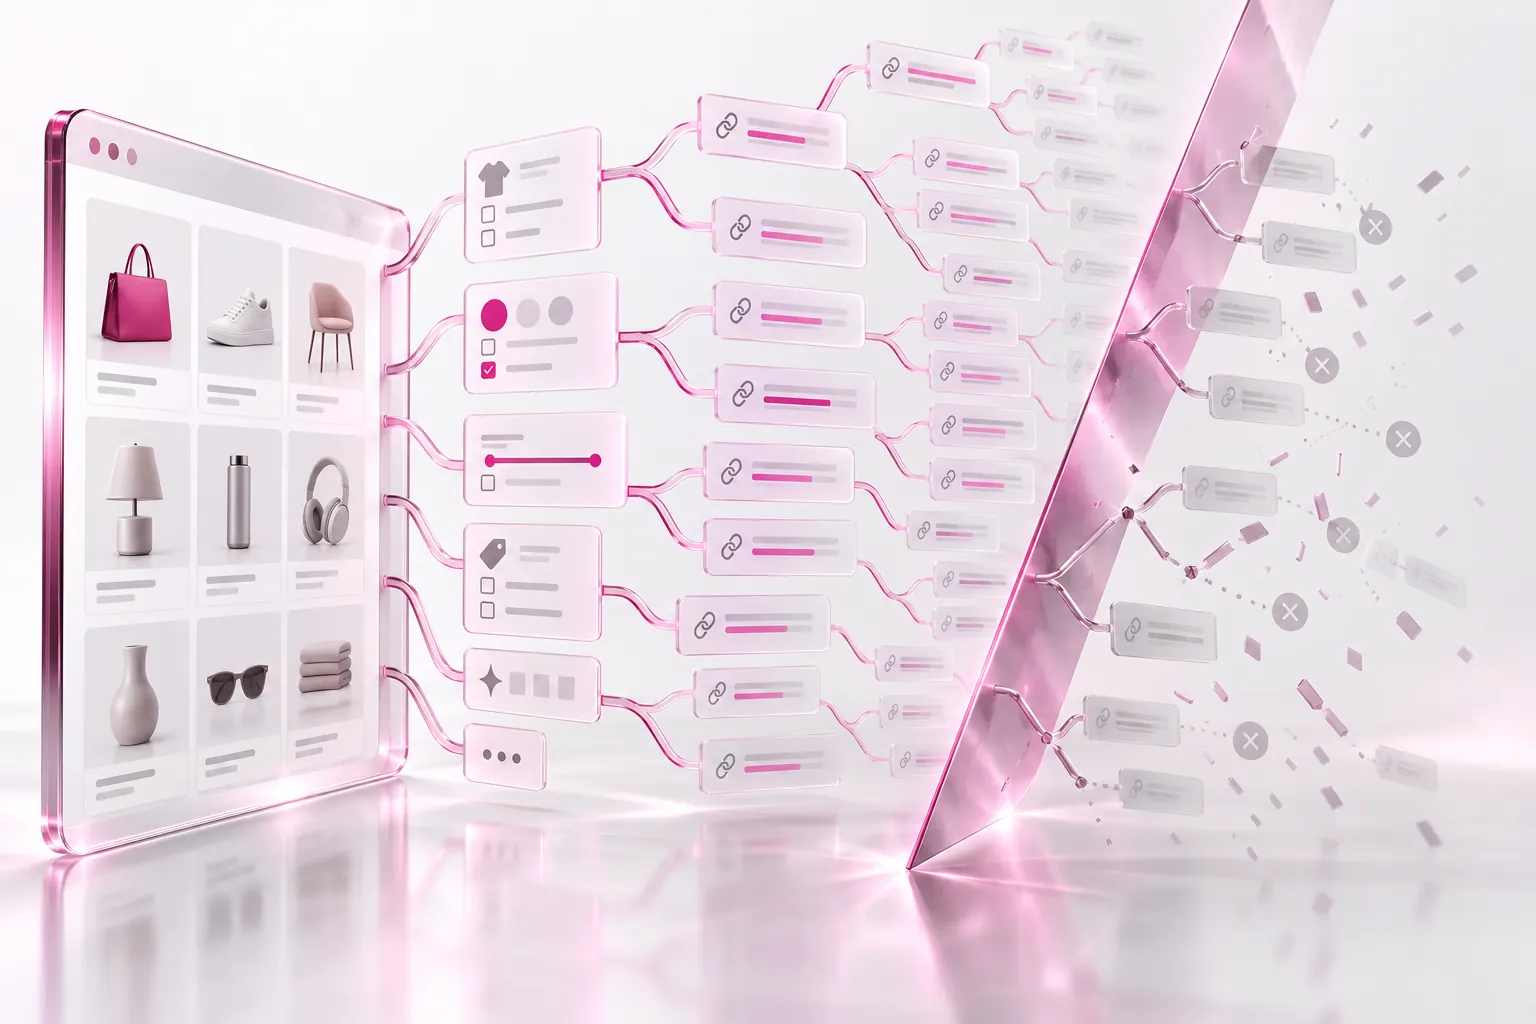
Decide which filtered pages deserve search visibility. If a class has no search purpose, prevent unnecessary discovery and crawling with a tested, durable rule. If selected combinations should be indexed, give them stable URLs, useful content, consistent internal links and valid responses.
Can robots.txt or a sitemap fix everything?
No. Robots.txt controls crawler access, while a sitemap suggests URLs for discovery. Neither repairs weak content, contradictory canonicals or poor internal links.
Use SAGEO's robots.txt audit guide before blocking patterns because a blocked page may still be known and a block can prevent Google from seeing a page-level noindex. Use the XML sitemap guide to keep canonical, indexable priority URLs in the sitemap.
What should be fixed first?
Fix the largest verified source of low-value requests that can be changed safely. Good candidates include endless filter combinations, internal links to redirected URLs, removed pages returning 200, or sitemaps containing unwanted URLs.
Change one pattern at a time. Save the current configuration, test representative URLs, define rollback and monitor host health, request mix and priority-page crawling. A smaller crawl count can be a success if a larger share reaches useful pages.
Limitations
Logs show requests, not rankings or business value. Search Console data can lag and may be aggregated. Crawling does not guarantee indexing, ranking, traffic, citation or conversion. The right control depends on the platform and the search value of each URL class.
What is the next sensible step?
Export a representative log window, classify requests by URL pattern and quantify the top source of waste. Ask SAGEO for a crawl efficiency audit when the fix crosses faceted navigation, templates, robots rules, sitemaps and deployment systems.
Sources
- Optimize your crawl budget, Google Crawling Infrastructure. Scope, capacity, demand and inventory controls.
- Managing crawling of faceted navigation URLs, Google Crawling Infrastructure. Filter URL risks and controls.
- Troubleshoot Google Search crawling errors, Google Search Central. Crawl Stats, logs and efficiency.
- Robots.txt: Block Crawling, Not Indexing, SAGEO. Related crawl-control audit.
- XML Sitemap: Does Google Need It?, SAGEO. Related discovery audit.